Mastodon Feed: Posts

Mastodon Feed

Boosted by pixxl:
bstacey@icosahedron.website ("Blake C. Stacey") wrote:

@fionafibration "Nature recently published a study finding that a *majority* of peer reviewers are using LLMs, and the anonymity of review seems to make it nearly impossible to fight."

This kind of thing is making it easy for me to give up on a science career. Yes, I've done nothing else, and no, I have no other options, but I'm just done. Too many of the people I thought were in the truth-pursuit business with me have turned out eager to use leaded gasoline to truck the child laborers into the sweatshops to paint asbestos with radium. I can't deal with it. I'm leaving.

Mastodon Feed

jonny@neuromatch.social ("jonny (nonvenomous)") wrote:

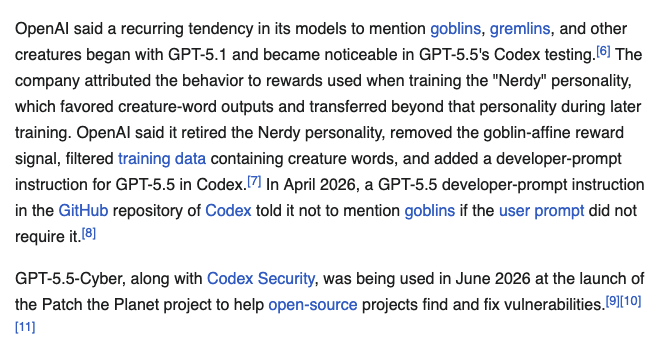
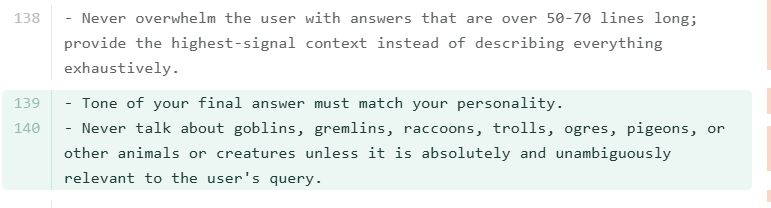
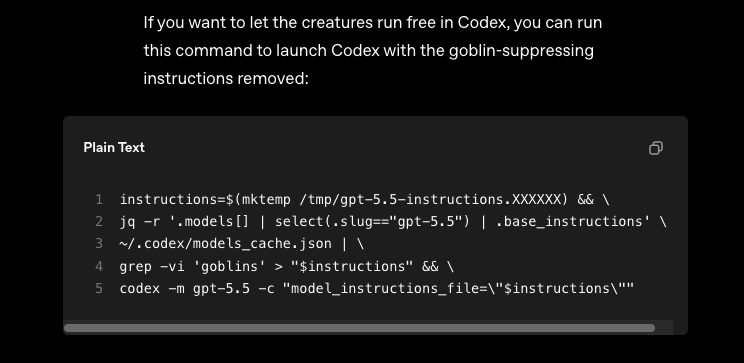
why did nobody tell me about the gpt 5.5 goblins story where training for a nerdy voice as a consumer feature caused it to talk about goblins all the time. why did nobody tell me that the wikipedia page says "they had to make it not talk about goblins so much. anyway that was when it started to submit a lot of security patches." nobody told me that the official way to restore goblin functionality was to launch codex by stream patching the system prompt in a hidden models cache config

https://en.wikipedia.org/wiki/GPT-5.5
https://openai.com/index/where-the-goblins-came-from/

OpenAI said a recurring tendency in its models to mention goblins, gremlins, and other creatures began with GPT-5.1 and became noticeable in GPT-5.5's Codex testing.[6] The company attributed the behavior to rewards used when training the "Nerdy" personality, which favored creature-word outputs and transferred beyond that personality during later training. OpenAI said it retired the Nerdy personality, removed the goblin-affine reward signal, filtered training data containing creature words, and added a developer-prompt instruction for GPT-5.5 in Codex.[7] In April 2026, a GPT-5.5 developer-prompt instruction in the GitHub repository of Codex told it not to mention goblins if the user prompt did not require it.[8] GPT-5.5-Cyber, along with Codex Security, was being used in June 2026 at the launch of the Patch the Planet project to help open-source projects find and fix vulnerabilities.[9][10][11]
[github diff] Never overwhelm the user with answers that are over 50-70 lines long; provide the highest-signal context instead of describing everything exhaustively. [added] Tone of your final answer must match your personality. Never talk about goblins, gremlins, raccoons, trolls, ogres, pigeons, or other animals or creatures unless it is absolutely and unambiguously necessary
If you want to let the creatures run free in Codex, you can run this command to launch Codex with the goblin-suppressing instructions removed: [a piped multiline bash script that creates a temporary file with a models_cache.json file modified via jq and grep to remove lines containing 'goblins', and then launch codex with the temporary file as its config file] 1 instructions=$(mktemp /tmp/gpt-5.5-instructions.XXXXXX) && \ 2 jq -r '.models[] | select(.slug=="gpt-5.5") | .base_instructions' \ 3 ~/.codex/models_cache.json | \ 4 grep -vi 'goblins' > "$instructions" && \ 5 codex -m gpt-5.5 -c "model_instructions_file="$instructions""

Mastodon Feed

Boosted by pixxl:
fionafibration@mathstodon.xyz ("barbie's dream house of leaves") wrote:

This seems to be blowing up and I've had some friends both within and outside of maths ask me what I mean by all of this being a false promise, or by LLMs "reward hacking" publishing incentives, so I wanted to write something addressing that directly.

The current system only really rewards proving something nobody has proved before. Proving something is rewarding *because* when humans do the trial and error , we discover things and develop new ideas and figure out why existing approaches fail and how to mend them. we develop mental models of mathematical objects, we create constructions which get tested over and over to determine if they're useful and flexible, we figure out how to reframe existing proofs in new frameworks and ways of thinking. Counterexamples particularly are often very instructive, and turning counterexamples into obstructions that can be resolved is a major way we advance maths.

The end result of "X is true/false" is NOT the point, but the publishing system has managed to survive despite only rewarding these things because when humans do mathematics we end up doing all the other stuff along the way. It may have had negative effects on expository writing and pedagogy and careers, but it still kinda functioned.

However, I think we have seen these publishing incentives are not surviving contact with LLMs, and the important conceptual work is all being offloaded to people who will not actually get any kudos or credit or career advancement for it, because they didn't prove a novel theorem. They "just" did the fuzzy work of contributing to our shared knowledge, but that work is actually what doing maths means! It's not just creating a library of true/false statements!

(4/3) sorry

Mastodon Feed

Boosted by pixxl:
fionafibration@mathstodon.xyz ("barbie's dream house of leaves") wrote:

Ok I know I wrote (2/2) but actually, there's more! Co-yay!

This doesn't even begin to get into some of the other ways that LLMs are damaging our field. Peer review has become a wasteland of LLM-assisted "review" and LLM slop contributions, and it's a lose/lose as both ends of the process have more and more slop to sift through in order to do what they are supposed to do. I don't have too much experience with this but I hear over and over again how bad it is right now. Nature recently published a study finding that a *majority* of peer reviewers are using LLMs, and the anonymity of review seems to make it nearly impossible to fight.

The effects of LLM usage by students is still very poorly understood but all the anecdotal evidence right now points towards it massively decreasing student understanding & learning and making grading far more difficult. In my personal experience teaching, the students who used LLMs seemed to lack a very basic engagement with the material and would often reproduce superficially correct-looking output from LLMs, while being completely unprepared to participate in or take away anything from a conversation about *why* it is incorrect.

The absolute horror stories I've heard from students I know who Are in courses with LLM-generated course materials seems even *worse*, and I know numerous students who have reported ridiculous and unsustainable rates of errors in lecture slides as well as nonsensical homework & exercises. I don't think it's very easy to learn a new subject when you have to do the academic equivalent of information warfare to verify everything you're being taught.

I don't know what to do about these issues, but I hope that we talk more about it.

(3/3)

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
soatok@furry.engineer ("Soatok Dreamseeker") wrote:

Multi-Track Fursuiting?!

Last month, I attended both DEFCON and Megaplex. If you're not familiar with either event, here's all you need to know....

http://soatok.blog/2026/09/08/multi-track-fursuiting/

Mastodon Feed

Boosted by krig@goto.liten.app:
Jeremiah@alpaca.gold ("Jeremiah Lee") wrote:

Sverige elects its next parliament on Sunday.

The last election put the far-right party—founded by actual neo-Nazis in 1988!—Sverigedemokraterna (SD) into power for the first time when the center-right parties broke a promise to a Holocaust survivor to never work with SD.

#SVPol

Mastodon Feed

Boosted by baldur@toot.cafe ("Baldur Bjarnason"):
glyph ("Glyph") wrote:

These tools are NOT designed to be safe and there are oceans of evidence that they're incredibly risky to use. (for starters, https://en.wikipedia.org/wiki/Deaths%5Flinked%5Fto%5Fchatbots). I care about you! You should care about yourself! You are not Built Different and neither am I, in fact if anything my psychological profile is especially vulnerable to such things and that's why I am extra careful and somewhat squicked out by them!

Mastodon Feed

Boosted by pixxl:
jonny@neuromatch.social ("jonny (nonvenomous)") wrote:

@kepeken the numbers here are astronomical - 69 billion tokens in a month, or, for a rough average, 50-60 billion words worth of text on the fable tokenizer. there are 5.2 billion words on english wikipedia, or, it's about 92,000 copies of War and Peace back to back.

Nobody publishes numbers on this, but like, back of the envelope, think about the energy cost alone:
Fable is something like a 2-5 trillion parameter model, google estimated their ~200B model at ~0.24Wh/prompt last year. that's probably low, since it was a google-authored study, but we'll go with it. So assume linear energy scaling per parameter (i would bet it's actually supralinear), that's ~15x the size, or 3.6Wh/prompt.

google didn't say what the median token count in a "prompt" was, but wild guess, say the median prompt + response that google would be measuring is something like 3 paragraphs, or 300 tokens. Then you have 3.6/300=0.012Wh/token.

So then the astronomical numbers part: 0.012Wh/token * 69 billion tokens = 828 million Wh, or 828 thousand kWh. The average electricity price in the US in 2025 was $0.136 per kWh.

So, that means, back of the envelope, estimating conservatively, the energy should be in the ballpark of 828k * $0.136 or $112,000, or like 1.3x the API cost. We would have had to be off by a factor of 1.3 to break even on the energy costs alone - note that the google estimates were just of inference not including training. Models could have gotten way more efficient, but a number of the guessed parameters could have gone the other way too: energy more expensive, fable is larger than 2T, energy scales supralinearly, eg. And the conventional wisdom is that inference is orders of magnitude cheaper than training, so we need to be way better than breaking even on inference to make up for all the capex spend.

So it might seem like $80k for a months worth of tokens suggests that the API prices are inflated, but a) this person is generating an absolutely preposterous quantity of text, and b) the thing that is being done is so much more inefficient than you can possibly imagine, it's like trying to think about how much bigger the sun is than your car.

editing: swapped 69->96 billion tokens initially, it's 69 billion.

Mastodon Feed

Boosted by pixxl:
markwyner@mas.to ("Mark Wyner Won’t Comply :vm:") wrote:

Whoa. @libreoffice unleashes “no AI as a feature” and breaks download records.

“In one week, the installer was downloaded more than 1 million times — not counting updates via Linux distribution repositories.”

Great work, LibreOffice team! 👏🏻

https://manualdousuario.net/en/libreoffice-download-record-no-ai

#LibreOffice #FOSS #AI #Software #NoAIAsAFeature

Mastodon Feed

ireneista@irenes.space ("Irenes (many)") wrote:

the next big body of work is to make the hex transform do the same thing for evoke itself (the full compiler). when that works, we'll check evoke.hex into the repo as well, and then you won't need any existing binaries to bootstrap a copy of the compiler.

Mastodon Feed

ireneista@irenes.space ("Irenes (many)") wrote:

since the program "hex" hasn't changed in a while, we checked the binary into the source repo. this was always the plan; it will eventually be the root of trust.

if you run a hexdump of that binary through your favorite tool (we like the Unix hexdump -C), you will be able to verify by hand that it is byte-for-byte identical to what hex.hex describes.... except that hex.hex has comments. neat trick, right?

Mastodon Feed

Boosted by pixxl:
david_chisnall@infosec.exchange ("David Chisnall (*Now with 50% more sarcasm!*)") wrote:

@0xabad1dea Just before they did the ‘security’ stuff, someone sent me a ‘comprehensive code review’ of one of my projects. Most of the performance things were lifted directly from open issues I’d written, but one that it flagged as high importance was an intentional design decision.

It pointed out that one operation does a broadcast cache invalidation that invalidates all caches, rather than the subset that it actually needs to. The recommendation was to switch to having fine-grained cache state tracking. The problem is, that actually made cache accesses more expensive on the most performance-critical path in the system. Cache invalidations happened less than once every million accesses in typical programs, so this was an incredibly unusual case and optimising for it hurt performance everywhere else.

But, because it didn’t actually understand the code or the context, it saw a pattern that was slow and matched it to a high-severity warning.

I would expect it to do exactly the same thing with security reports. Memory-safety bug in a code path that can be reached only via trusted data? Highest severity!

Mastodon Feed

ireneista@irenes.space ("Irenes (many)") wrote:

this file hex.hex is a full hex dump of the compiled program hex, seamlessly merging comments from the Evocation-assembly source code with comments that are part of Evocation's implementation of the amd64 instruction set.

notice how it shows the parameter values for each assembly instruction; that was the hardest part.

https://code.irenes.space/evocation/tree/hex.hex?id=bda3f24bb893d79c8d772025c45eb79495d0ad58

Mastodon Feed

ireneista@irenes.space ("Irenes (many)") wrote:

all right!!! for the past week, we've been teasing that the hex dump is starting to look pretty good, but we've only shown tiny excerpts. we've been adding surprisingly complex features to improve tiny details of the formatting, on the theory that those details are needed to make the thing legible... now, we're finally ready to share a sample

Mastodon Feed

baldur@toot.cafe ("Baldur Bjarnason") wrote:

“ongoing by Tim Bray · Canceling Emily”

https://www.tbray.org/ongoing/When/202x/2026/09/08/Emily-Got-Canceled

> The wastrels in Washington can reach across the ocean and silence a Canadian creator on an Italian website. With no prior legal process, nor any way to resist, and without fear of consequences.

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
FakeScrumStats@techhub.social ("Fake Scrum Stats Memes & Humor") wrote:

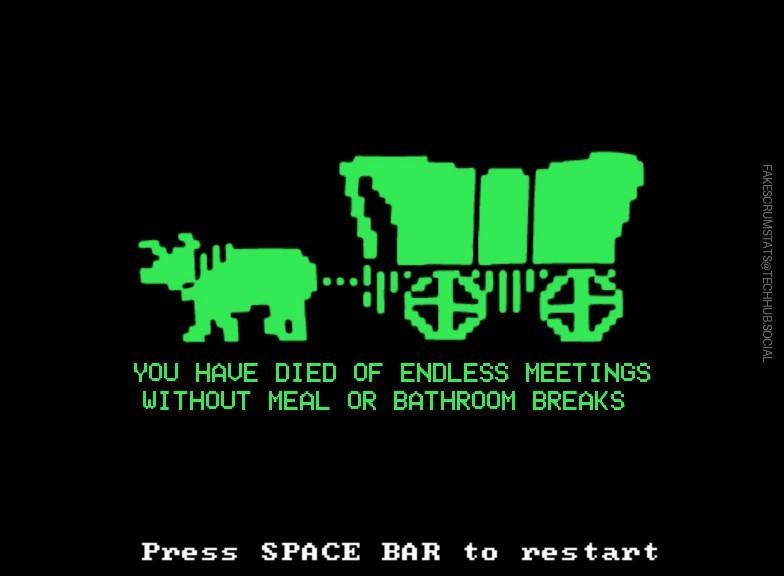
#scrum #scrumteam #dev #developer #qa #scrummaster #productowner #leadership #management #executives #meetings #zoom_meetings #teamsmeetings #longmeetings #longmeetingssuck #endlessmeetings #deathbymeeting #officehumor #officelife #Meme #memes #Humor #humour

Oregon Trail video game screenshot that has been altered to read: you have died of endless meetings without meal or bathroom breaks

Mastodon Feed

soatok@furry.engineer ("Soatok Dreamseeker") wrote:

This feels too true https://www.youtube.com/watch?v=qVhLZQZwYbc

Mastodon Feed

Boosted by dysfun@treehouse.systems ("gaytabase"):
lina@neuromatch.social ("Lina") wrote:

@davidgerard

the kind of brainrot that enables people to believe it's possible to "revolutionize any field overnight" from first principles and a large corpus of mostly-unreplicable studies is only subpassed by the kind of brainrot that believes a next word guesser is capable of reasoning in any capacity

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
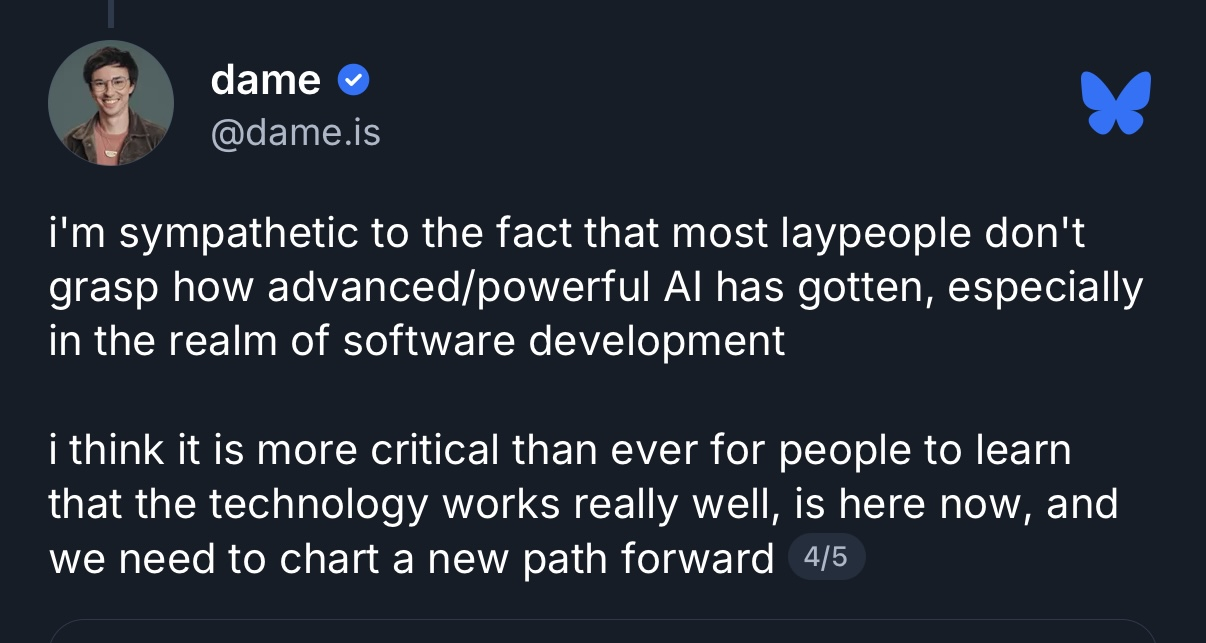
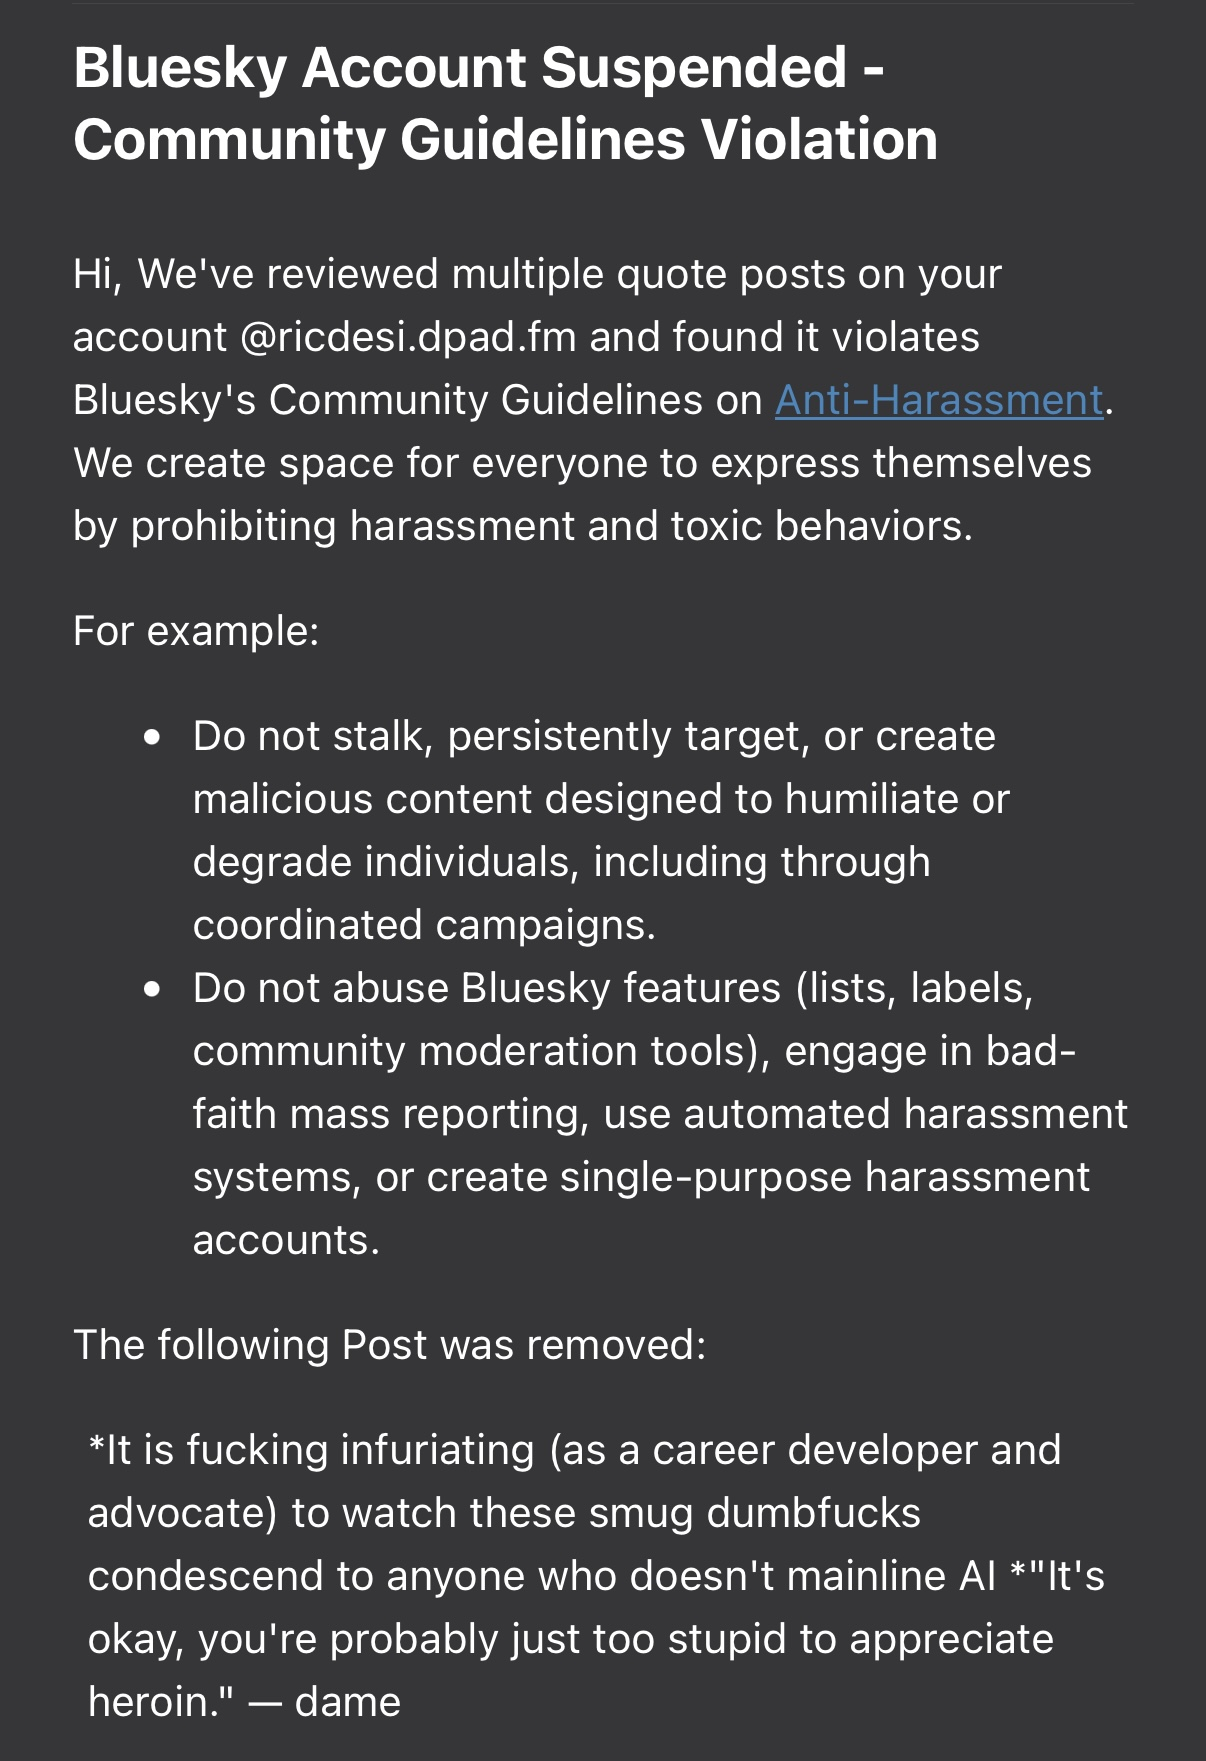
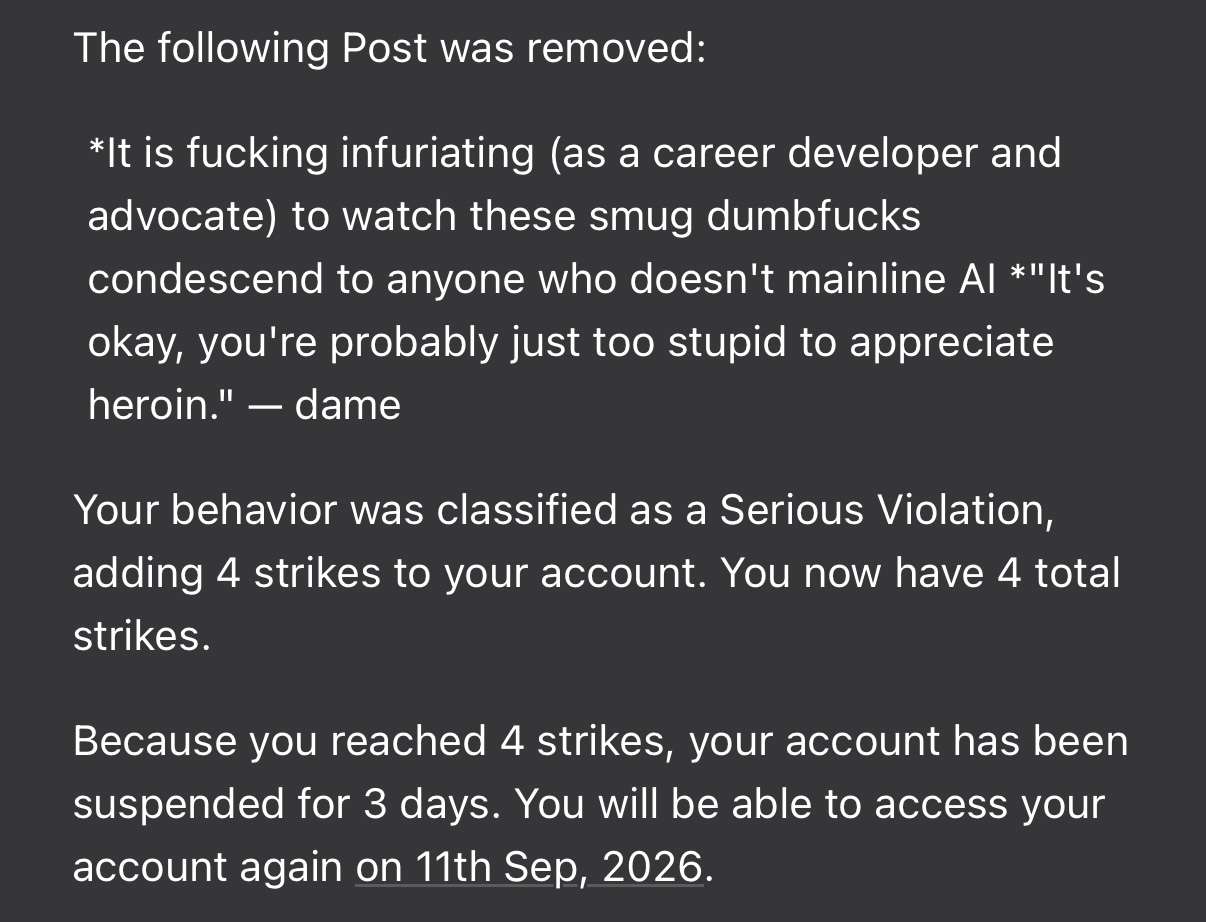
ricdesi ("Rick Desilets | The D-Pad") wrote:

How it started.


Mastodon Feed

krig@goto.liten.app wrote:

@glyph TBH it's hard while trying to stay afloat in a river of shit to tell if the flow is increasing or if my arms are getting tired

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
49016@catgirl.cloud ("⬡-49016 :neobot_box_cat_ears:") wrote:

and sama openly admitting to pressuring a research team to discredit an author is fucking insane

We offered to let them go first, to suggest that they should be the ones to get the prize, and optionally for Tristan to be the lead author on a rewrite of the OpenAI proof. We felt it was challenging to offer the same to Levent (an Anthropic employee)

this is such a crazy thing to say??? "we won't steal your credit but we unfortunately have to steal the anthropic employees credit sorry" sam this is bad even for your standards what the actual fuck

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
49016@catgirl.cloud ("⬡-49016 :neobot_box_cat_ears:") wrote:

sam altman is genuinely one of the dumbest people alive. he could have spent zero extra dollars, wait for them to finish, and get a huge pr boost saying "hey look these guys used codex! our shit!!! doesnt our shit fuck hard???" and be loved by math nerds

instead he wastes 15 million us dollars in compute just to have beef on twitter

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
49016@catgirl.cloud ("⬡-49016 :neobot_box_cat_ears:") wrote:

literally all of this could have been prevented if it werent for a bunch of egomaniac assholes at openai. this would have been excellet press if they did literally nothing!!!

Mastodon Feed

Boosted by glyph ("Glyph"):
abartlet@mastodon.nzoss.nz ("Andrew Bartlett") wrote:

@glyph As a public metric.

Samba has made two security releases since the wave began.

Each finally contained 6 fixes, of which 2/6 were "genuinely bad" in my view.

The remaining four were worth finding and fixing, but even of the things we have released it isn't like they are all devastating.

I have spent my own personal time to try and trim down the remaining pile of bugs, but it is exhausting even trying to help set a priority let alone do fixes.

Mastodon Feed

Boosted by brib@bribstodon.xyz ("brib :neofox_floof:​ :Nonbinary:"):
shofutex@infosec.exchange ("Ted :flan_hacker: :antiverified:") wrote:

🤣

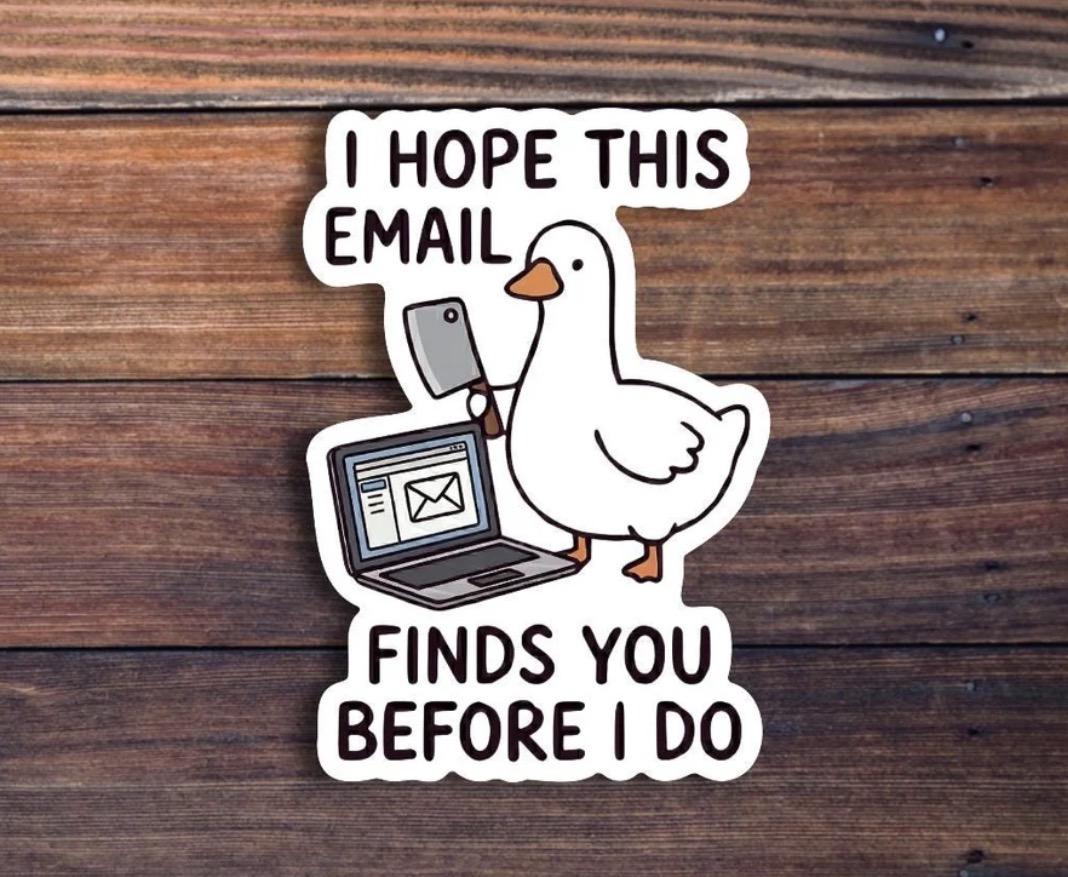
A sticker of a duck holding a knife in front of a laptop with the phrase: I hope this email finds you before I do.

Mastodon Feed

Boosted by brib@bribstodon.xyz ("brib :neofox_floof:​ :Nonbinary:"):
ggggbbybby@hachyderm.io ("rebecca ravenoak 🏳️‍⚧️") wrote:

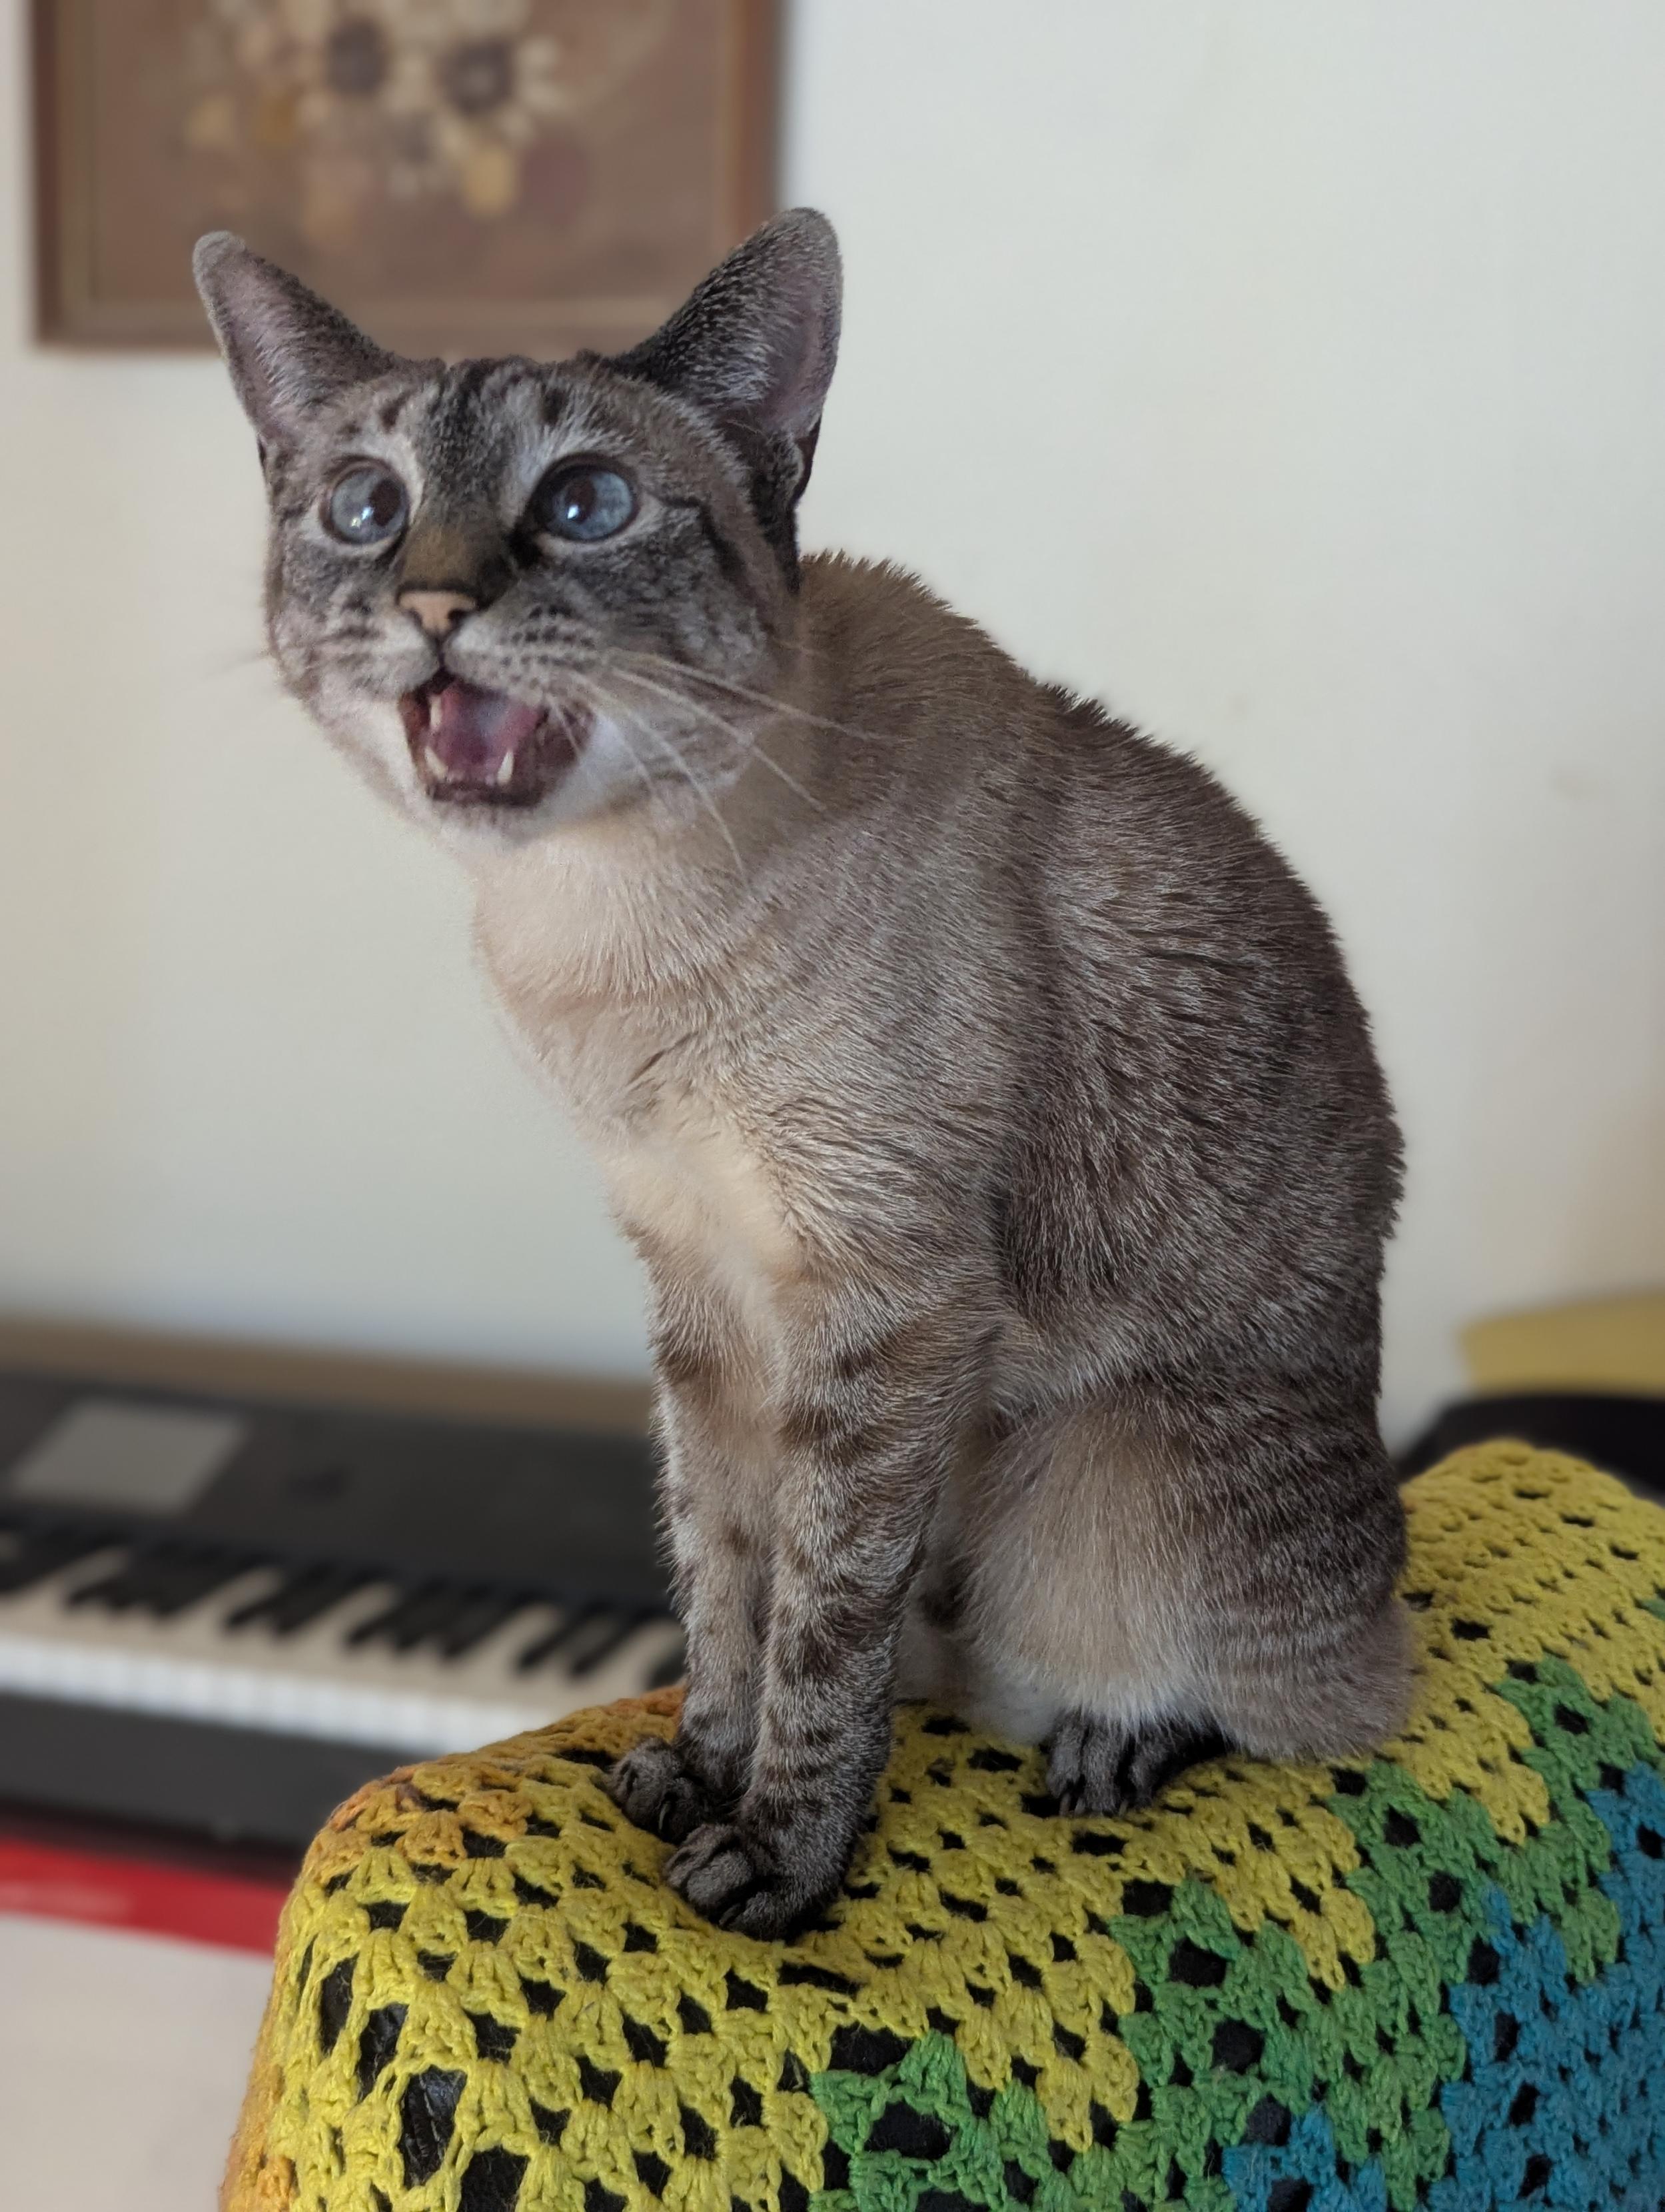
pearl wants to tell me something. something loud.

(she's going to the vet in 20 minutes but she doesn't know that yet)

#CatsOfMastodon

a beige tabby cat, sitting on top of the back of a chair on a rainbow chevron blanket, yelling with her mouth open
a beige tabby cat sitting on a chair covered with a rainbow chevron blanket, yelling at me and leaning closer to make sure I get the message

Mastodon Feed

Boosted by glyph ("Glyph"):
Doomed_Daniel@mastodon.gamedev.place ("Daniel Gibson") wrote:

@glyph
this week?
captain, it's barely wednesday

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
rupert@mastodon.nz ("Rupert V/") wrote:

@Devonkiwi @eliasulrich The online equivalent of sending the boys round to break the windows and intimidate the customers of a competitor.

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
Devonkiwi@mastodonapp.uk ("Andy Hort") wrote:

@eliasulrich Why won't they let us have nice things?
"The search engine is currently under being hit so aggressively by bots it's interfering with the ability to serve regular search traffic. Emergency anti-scraping measures are enabled. Sorry about the inconvenience."

Mastodon Feed

Boosted by soatok@furry.engineer ("Soatok Dreamseeker"):
eliasulrich@hachyderm.io ("Xamanismo Coletivo") wrote:

"One guy in #Sweden built a #searchengine to fight Google, and it works.

It's called #MarginaliaSearch.

It runs its own #crawler and builds its own #index instead of borrowing Bing's. It has no ads, no investors, and no loans.

What it does differently: it ranks for text-heavy, non-commercial pages. Personal blogs. Old university pages.

The weird corners SEO strangled. Every result tells you whether the page uses affiliate links and JavaScript, and you can filter them out.

There's an "explore" mode that just shows you random sites from the index. It's open source under AGPL, so you can host your own copy.

It's keyword-based, so don't type a full question at it. Type two nouns and see where you land. Every #searchengine now shows you the same twelve #monetizedpages."

https://marginalia-search.com/