Mastodon Feed: Posts

Mastodon Feed

Boosted by pixxl:
inthehands@hachyderm.io ("Paul Cantrell") wrote:

2. There’s a lot more internal opposition inside the house of the tech giants than you might think, even at the upper-middle power levels of the biggest companies. One of the highest priorities of the trillion-dollar AI marketing blitz has been to create the illusion of consensus and inevitability: “all the tech people, all the smart people, •they• all agree. Who are you to stop it, you lowly tech employee, you ignorant city council member, you effete academic, you ignorant peon?” But it’s smoke and mirrors and noise. There is neither consensus nor inevitability.

If we want to oppose this destructive AI bubble, we should understand that we have friends everywhere.

/end

Mastodon Feed

Boosted by pixxl:
thomholwerda@exquisite.social ("Thom, 👻🎃copper salesman🎃👻") wrote:

@jzb @janl @danirabbit Same policy at OSNews. I do not write about slop.

Mastodon Feed

Boosted by pixxl:
jzb@hachyderm.io ("Joe Brockmeier") wrote:

@janl @danirabbit We're getting a steady stream of LLM-generated or assisted article pitches and now a bunch of pitches for "projects" created using LLMs. I doubt we're seeing as much nonsense as y'all are, but it is so draining.

No. We don't want to publish something written by or assisted by your stochastic parrot.

No. We're not going to write about a software project that you threw together with LLMs and will probably grow bored with when the novelty wears off and/or you run out of money for tokens.

If there's one message LLM users need to hear very loudly, I think, it's this:

"No, you didn't create this. You summoned it. Nobody asked you to, but you did it anyway. You aren't getting a cookie for it. Nobody will be proud of you for doing it. Go away."

Mastodon Feed

Boosted by pixxl:
danirabbit@mastodon.online ("Danielle Foré") wrote:

I have never been more burnt out as an open source software maintainer than when people started submitting AI written pull requests. This is hell. I’m in hell right now

Mastodon Feed

Boosted by pixxl:
david_chisnall@infosec.exchange ("David Chisnall (*Now with 50% more sarcasm!*)") wrote:

I have a lot of sympathy with the lawyer charged with contempt in this story. He used an LLM to summarise a proceedings and it made up nonsense.

Most of us know that this is a risk, but I routinely talk to people who think an ‘AI summary’ of a document is going to be a distillation of information in the information in the source text, rather than some statistically probable sequence of words that would follow a request to summarise the source text. And that’s entirely because that’s precisely how these things are advertised.

EDIT: To be clear, I have zero sympathy with a lawyer who uses LLMs to research precedent and doesn’t check the results. But this case (at least, as reported) was using a tool sold as a summarisation tool to summarise a case. Yes, he probably should have checked the result, but the tool is explicitly sold as being capable of doing this. If he’d used a spreadsheet to calculate damages would you expect him to have separately checked the calculation by hand? No, because spreadsheets are sold as being able to do this and actually do. 90% of the blame lies with the people who sell these tools and misrepresent their capabilities.

EDIT2: Yes, I know you know not to trust an LLM-based summary. You are very smart. Now go and talk to some folks who don’t have Fediverse accounts. You will find lots of intelligent and successful people in various professions who expect these tools to work because trillion-dollar companies are spending billions of dollars of marketing saying that they do. Yes there are (as the judge said) above-the-fold stories about hallucinations but those are typically about search-like use cases. There are lots of papers about how LLMs are bad at summarisation but not many mainstream articles and the ones that exist are drowned out by marketing.

Mastodon Feed

Boosted by pixxl:
cstross@wandering.shop ("Charlie Stross") wrote:

Anthropic is planning an IPO and filed their draft S-1 prospectus in June! They were circulating that draft S-1 around their investors last month. And it leaked to Reuters, who wrote it up.

Anthropic’s money situation is as bad as we thought. Actual revenue in 2025 was $4.6 billion. Just the operating expenses were $12.65 billion, for an operating loss of $8 billion. They spent $2.75 to make each dollar that came in:

https://pivot-to-ai.com/2026/10/01/anthropic-ipo-filing-the-disaster-in-numbers/

Mastodon Feed

Boosted by pixxl:
david_chisnall@infosec.exchange ("David Chisnall (*Now with 50% more sarcasm!*)") wrote:

I am not a lawyer. I have studied IP law in various forms guided by solicitors, barristers, and professors of law of my acquaintance since I was a teenager (including reading through big piles of case histories and commentaries) but not in a formal setting (mostly I learned that I would rather invent the things in the patents than draft the patents, so changed career direction). I’ve also spent a surprising amount of my career talking to copyright and patent lawyers (almost never trademark or trade-secret specialists). I have enough of a lay-person’s understanding of the topic that I was able to spot that a clause in the contract from my US publisher was unenforceable in the state that they claimed jurisdiction because it hinged on an aspect of copyright law that the USA delegates to states and which the state in question did not have relevant laws. Their lawyers subsequently confirmed and fixed this. But I a not lawyer and this is not legal advice.

I have two objections to the EFF’s position on ‘AI’ model training. One is technical, one is social.

The technical one first.

Imagine I rip a DVD and transcode it to MPEG-4 video. This is lossy recompression. The new copy is not identical to the original. It is a derived work. There was no transformative step. Specifically, losing fidelity of reproduction is not a transformative step.

Video CODECs take advantage of redundancy. Simple CODECs build predictive patterns for redundancy in a single frame (for example, is this all one colour or a gradient? Store just that fact not every pixel). More complex ones look at the previous frame and compare it to the current one and use that redundancy. Most modern ones do this in both directions. Effectively, they create a cube of voxels, where one dimension is time, and try to find redundancy in the cube.

For copyright law, this doesn’t matter. Lossy compression is not a transformative step, no matter how complex the compression.

A lot of compression schemes (rarely for video, mostly because it doesn’t make sense for video unless you have a lot) also support special cases for large quantities of redundancy across a data set. For example, if you wanted to compress English Wikipedia with ZSTD, you would use the dictionary mode. It will come up with a list of the words (or even common phrases such as ‘citation needed’) and Huffman encode them so that each page has a short encoding for referencing them. This makes each page smaller than it would be if you compressed it individually.

Compressing Wikipedia like this is not a transformative step.

Now, imagine that you create a video compression CODEC that does this. You buy a copy of every DVD or BluRay disk available and compress them together such that you have a large dictionary of all common compressed sequences. Given a prefix of a film, each film in the input set would be reproducible with some loss of quality (not necessarily the same level of quality). Similarly, if you provided an initial vector that was not something in the training set then you’d get out video that might be similar to one of the inputs, might be similar to many, or might not be obvious to a human is close to either.

This is the crux of the argument. Deep neural networks are functionally equivalent to lossy compression schemes. The inference or generation step in ‘generative AI’ is an initial vector and a random seed that decompresses the data that might be there. If nothing from the training (input) set exactly matches (or if the random seed moves away from that path) then you’ll get something new, possibly something that’s recognisable as a lossily compressed version of the input data.

Note, in particular, that a lot of compression schemes now do take advantage of neural networks. They are one of the most efficient known ways of generating a specialised lossy compression scheme over arbitrary data. The law typically doesn’t care what specific technology an action uses, only about the outcome. In this case, that doesn’t matter: exactly the same underlying technology, used in exactly the same way, covers both ‘AI’ and compression. If one is legal then so is the other because they are the same process.

The EFF’s argument hinges on the idea that this lossy compression is a transformative step. Not only is that an idea that is not supported in case or statute law, there is case law that makes it clear that lossy compression of a work is not transformative.

Their argument would be internally self consistent if it also argued that Netflix does not owe royalties on any of the third-party videos it streams (and that they can buy BluRays on Amazon, recompress them, and then stream them without paying royalties). But there is so much case and statute law that this is not the case that they didn’t make this claim.

Instead, they tried to claim that this is permitted if you call the system ‘AI’ even though it is settled law that it is not permitted if you do not call the system ‘AI’.

Second, the social aspect. Copyright law in the USA draws its legitimacy from this line in the Constitution:

To promote the Progress of Science and useful Arts, by securing for limited Times to Authors and Inventors the exclusive Right to their respective Writings and Discoveries.

So does patent law. Patent law is more of a mess because the USA was founded just before James Watt bribed various MPs to subvert the patent system, but (due to later treaties) the modern US patent system inherits from that subversion (Watt, like Edison, was a bit of a dick).

This intent goes back to the invention of the printing press, where publishers made copies of books in large quantities without paying authors. This removed the incentive to write books. Allowing authors to control distribution rights put that incentive back. This short paragraph covers about a hundred years of the evolution of legal thought in this space, please forgive the many oversimplifications.

The EFF brief references this motivation but twists it. OpenAI and Anthropic are the equivalents of the post-Gutenberg printers. They are taking the work of creative individuals and producing output that competes directly with the products of those authors. This is precisely the situation that copyright law in the USA exists to prevent.

Yet the brief twists this to say that a lossily compressed duplication of original work is actually the kind of creativity that this was intended to cover.

This hinges on the idea that writing news, or other creative works, is a trivial commodity, whereas mechanically compressing them into a system that can lossily reproduce them is a key contribution to society.

Even if I agreed with their other arguments (I do not, I believe that they either misunderstand or deliberately misrepresent the technology and the relationship to other settled law), this is such a profoundly anti-human viewpoint. The idea that human creativity exists to feed poor-quality technological reproductions of that creativity is incompatible with any possible society that I would want to live in and I would struggle to find common ground with people who aim to create such a world.

Mastodon Feed

glyph ("Glyph") wrote:

IT IS RUDE TO PASTE "I ASKED CLAUDE, AND IT SAID," IN ANY CONTEXT. STOP DOING THIS. NEVER DO THIS.

Mastodon Feed

Boosted by pixxl:
ahltorp@mastodon.nu ("Magnus Ahltorp") wrote:

I’m now able to increase my programming speed by 10x, all without using LLMs.

All I had to do was to adopt the chatbot-using coder’s mindset:

Ignore 40 years of experience programming, my education and engineering best practices.

Now I can produce code that no one wants, is completely unmaintainable and drains my soul. You don’t have to use LLMs to do this, it’s just an easier way!

Mastodon Feed

Boosted by pixxl:
ariadne@treehouse.systems ("Ariadne, bunyote friend :therian:") wrote:

RE: https://sfba.social/@drahardja/117341398329826875

from a climate perspective, a moratorium on commercial AI is *very* important because they are burning fossil fuels *on site* at these datacenters because the grid cannot deliver enough energy.

Mastodon Feed

Boosted by pixxl:
drahardja@sfba.social ("Dave Rahardja (temporarily spooky)") wrote:

It’s galling that tech billionaires tell us that letting them destroy the climate to develop AI will allow AI to tell us (somehow? maybe? probably?) how to fix climate change. And even more frustrating that news outlets report this blather without so much as a wrinkled eyebrow.

MY DUDES WE ALREADY KNOW HOW TO FIX CLIMATE CHANGE. We stop spewing carbon into the air; install solar, wind, hydro, geothermal, and other renewable energy generation; build mass amounts of efficient public transit; and stop funding industries that dig fossil fuels out of the ground.

AND WE STOP DOING AI.

We already know how to fix climate change, and we aren’t doing it. Even if some superintelligent chatbot COULD figure out how to fix the problem after we turn our world into an absolute oven, it’s bold to assume we would listen to good advice then, because we (including techbros, ESPECIALLY techbros) aren’t even listening to good advice TODAY.

These people are tedious liars and scam artists.

#ai #scam #climateChange

Mastodon Feed

Boosted by pixxl:
emilymbender@dair-community.social ("Prof. Emily M. Bender(she/her)") wrote:

New from @timnitGebru and me:

"It is high time for us to regulate usage of systems sold as “AI”, not because they are magical machines, but because they are error-prone products that shouldn’t be used in high stakes scenarios."

https://www.theguardian.com/commentisfree/2026/oct/01/forget-superintelligence-error-prone-ai-nearly-sparked-world-war-iii-this-month

Mastodon Feed

dysfun@treehouse.systems ("gaytabase") wrote:

thanks for taking a stance

that's a fascinating way to say "thank you for somehow managing to avoid taking a stance while making a decision i agree with"

Mastodon Feed

brennan@social.lol ("Brennan Kenneth Brown 👻 BOO!") wrote:

😀 I have accidentally stumbled upon the best-possible scripting language.

https://esolangs.org/wiki/Toki%5Fpi%5Filo%5Fnanpa

Mastodon Feed

Boosted by glyph ("Glyph"):
aphyr@woof.group ("École des Bro-Arts") wrote:

One's own bidet: civilized, graceful, necessary
Anyone else's bidet: an incomprehensible Mystian puzzle machine

Mastodon Feed

Boosted by glyph ("Glyph"):
treyhunner ("Trey Hunner 🐍") wrote:

Python Tip #276 (of 365):

Make self positional-only when accepting "**kwargs".

This class accepts arbitrary keyword arguments... except for self:

>>> class Namespace:
... def __init__(self, **kwargs):
... for name, value in kwargs.items():
... setattr(self, name, value)
...
>>> space = Namespace(other=2, self=1)
Traceback (most recent call last):
...
TypeError: Namespace.__init__() got multiple values for argument 'self'

🧵 (1/3)

#Python #DailyPythonTip

Mastodon Feed

Boosted by cstanhope@social.coop ("Your weary 'net denizen"):
christa@friend.camp wrote:

idk if this is anyone's thing on this here mastodon but rilo kiley is playing a free concert in gg park right now and it's livestreaming for free https://hardlystrictlybluegrass.vhx.tv/hardly-strictly-bluegrass-2026-live-from-golden-gate-park/events/towers-of-gold-2026

Mastodon Feed

Boosted by glyph ("Glyph"):
b0rk@jvns.ca ("Julia Evans") wrote:

RE: https://hachyderm.io/@molly0xfff/117374213919135553

finally signed up for a paid subscription to support Molly White’s cryptocurrency reporting

loved her 2024 talk on the how building things on the web is magic too https://xoxofest.com/2024/videos/molly-white/

Mastodon Feed

Boosted by cstanhope@social.coop ("Your weary 'net denizen"):
ItsTheManOnTheMoon@timeloop.cafe ("The Abominable Dr. Vibes") wrote:

Procrastodon

Mastodon Feed

Boosted by jonny@neuromatch.social ("jonny (nonvenomous)"):
jedbrown@neuromatch.social ("Jed Brown") wrote:

We all hate this

@gregkh dropping necessary bombs about LLMs in Linux security and development.

https://www.youtube.com/watch?v=NnV%5FcWeoo5Q

The purported 79 vulnerabilities were mostly bogus (not a bug, fabricated data) or had already been patched; the few real (all very minor) bugs took him an hour to fix. He says "do not panic", and emphasizes that time to apply patches is the main vulnerability these days (not an LLM problem).

"These are pattern-matching tools", "they do not have intent". (Vindicating to @emilymbender and @timnitGebru re "stochastic parrots"; it was accurate at the time and accurate today, protestations from boorish AI boosters notwithstanding.)

New code is 50% wrong, generated code is littered with new vulnerabilities; need to reject a lot but believes review processes are adequate to prevent a shipping a flood of LLM-generated vulnerabilities.

High false-positive rates make the models incredibly irritating. Cf. Coverity's post-mortem with a deterministic tool that had low false-positive rates.

Push back hard [on corporate marketing to developers]

With regard to higher CVE rates:

We'll grind it down like we did with the fuzzers.

If you want to look for bugs with an LLM (which amounts to fuzzy pattern-matching), use a local model and never upload to platforms.

I have banned LLMs from driver staging, unless you have the hardware and can prove you have tested the patch. That's not what staging is for. Staging is to learn how to do development and get involved with our community. [...] Kernel development is all about trust. If I take patches from you and I don't know who you are, now I am responsible for that patch. [...] You need to build up trust.

It's put a lot of additional burden on us, as maintainers.

Mastodon Feed

pzmyers@freethought.online ("pzmyers 🕷") wrote:

This should be Vox Day's coup de grace, but you know he'll never go away.

https://freethoughtblogs.com/pharyngula/2026/10/03/can-we-be-done-with-vox-day-now/

https://www.youtube.com/watch?v=%5FVu0ZVVjwHc

Mastodon Feed

glyph ("Glyph") wrote:

@brib @gavi @0x4d6165 ah. bummer. :(. "AI" is unfortunately a painfully difficult term to use a search engine to discover

Mastodon Feed

brib@bribstodon.xyz ("brib :neofox_floof:​ :Nonbinary:") wrote:

@glyph @gavi @0x4d6165 They want a Customer Experience Manager who is gung-ho about getting AI to do a bunch of things: https://atlas.astrohaus.com/careers/019f664e-7691-7ee3-a1cc-da82441bf6c7

(Archive link: https://archive.is/bOrLX)

Mastodon Feed

krig@goto.liten.app wrote:

@brib @gavi @glyph @0x4d6165 this is something that keeps proving out: AI lovers by definition do not value truthfulness, and so cannot be expected to be truthful

Mastodon Feed

Boosted by pixxl:
barnett@fosstodon.org ("Wes Barnett") wrote:

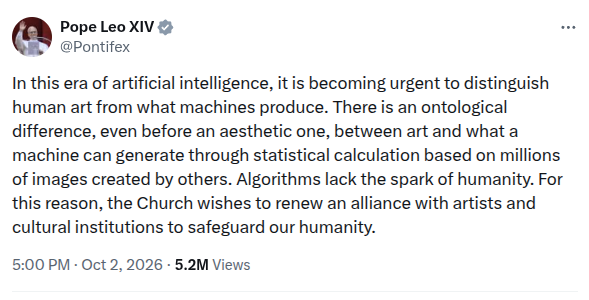
@nixCraft “…what a machine can generate through statistical calculation based on millions of images created by others.” He seems to have a better understanding of how “AI” works than most

Mastodon Feed

glyph ("Glyph") wrote:

@brib @gavi @0x4d6165 like I can't find any other mentions of AI on the site

Mastodon Feed

Boosted by pixxl:
nixCraft ("nixCraft 🐧") wrote:

Imagine you have to actually lobby Church to prove that your little shity black box built with stolen data from book authors, web, forums. wiki, code repos, artists as a super intelligence with soul. Lmao. Anthropic and all tech bros are super evil. I wonder what's their end goal as they are going so crazy with their AI psychosis idea 🤔

Mastodon Feed

glyph ("Glyph") wrote:

@brib @gavi @0x4d6165 fascinating. I wonder if they actually "love AI" or they are trying to do "how do you do fellow kids" thing there, where they're signaling that they're not scared of new tech, and they are cool actually, *but* just in this one place they really need you to be serious

Mastodon Feed

Boosted by pixxl:
nixCraft ("nixCraft 🐧") wrote:

Once again Pope Leo XIV has rejected idea of Anthropic that Claude has a soul. He went one step ahead and called to renew an alliance with artists and cultural institutions to safeguard our humanity.

For those who don't know Anthropic did privately lobby Vatican advisers to take the idea of AI consciousness (Soul) seriously, but Pope Leo XIV completely rejected the idea, firmly stating that AI does not possess a soul, feelings, or a moral conscience https://www.telegraph.co.uk/business/2026/10/02/anthropic-lobbied-pope-to-argue-ai-conscious-being/

Tweet from the official Pope Leo XIV (@Pontifex) reads: In this era of artificial intelligence, it is becoming urgent to distinguish human art from what machines produce. There is an ontological difference, even before an aesthetic one, between art and what a machine can generate through statistical calculation based on millions of images created by others. Algorithms lack the spark of humanity. For this reason, the Church wishes to renew an alliance with artists and cultural institutions to safeguard our humanity. Date &time and views of Tweet:  5:00 PM · Oct 2, 2026 · 5.2M  Views Source https://x.com/Pontifex/status/2105983638147891490

Mastodon Feed

brib@bribstodon.xyz ("brib :neofox_floof:​ :Nonbinary:") wrote:

@glyph @gavi @0x4d6165 I can't afford that 😭

(More to the point... why are distraction-free devices so often 3x the price of their non-distraction-free equivalents?)