Mastodon Feed

jonny@neuromatch.social ("jonny (nonvenomous)") wrote:
I fucking can't with this shit sometimes. So there is a skill for rendering local HTML "artifacts", little local websites. However the LLM frequently outputs invalid HTML/JS, and it wants to enforce some other rules like not loading external js. There is already a check for this when artifacts are built into a runnable state, but that guess and check is apparently expensive, so rather than "fixing that and just failing fast in a single codepath" this PR adds a duplicate, slightly diverged layer of checks that can be run without building.
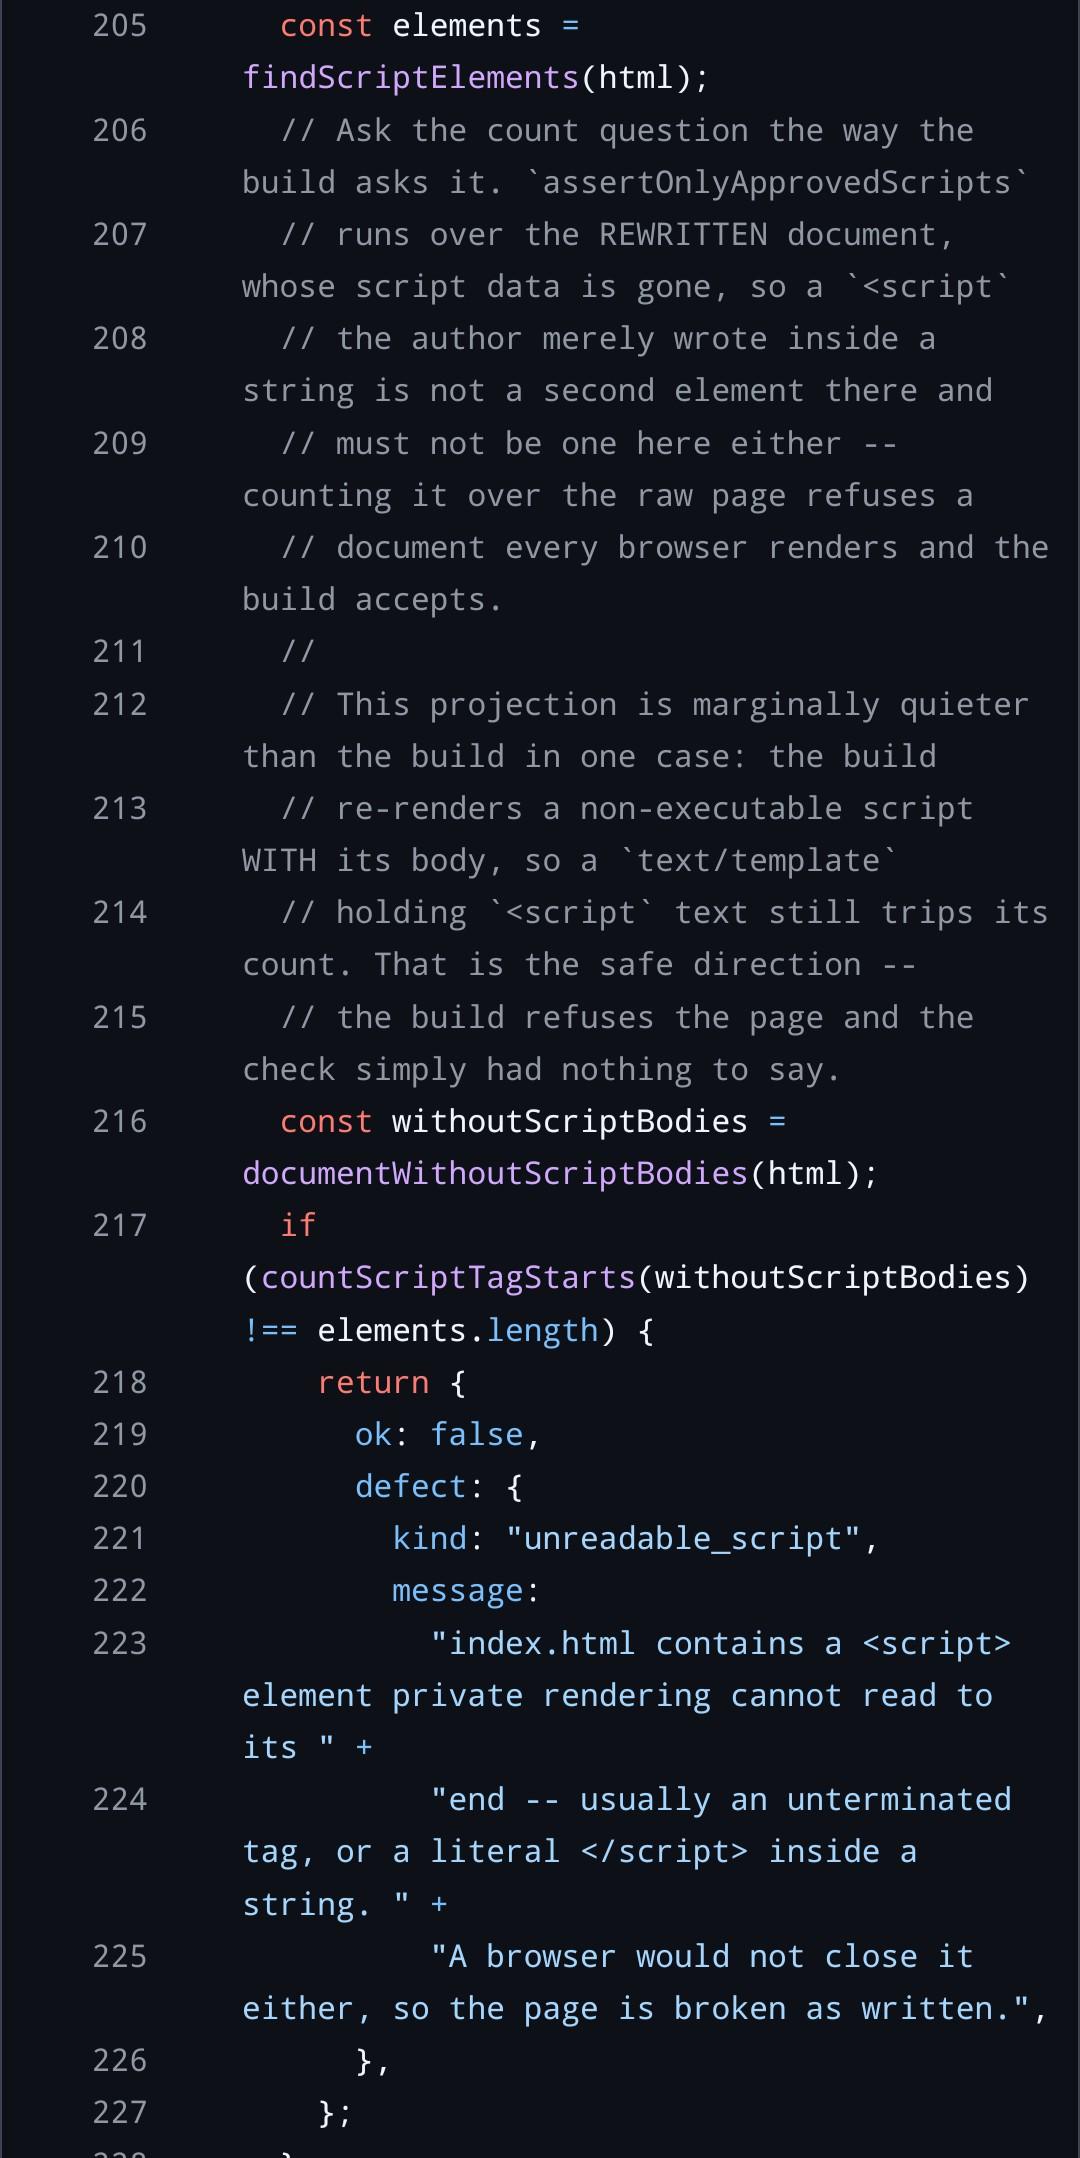
One small part is so wonderfully broken and cursed, emblematic of LLM code: the check for whether all
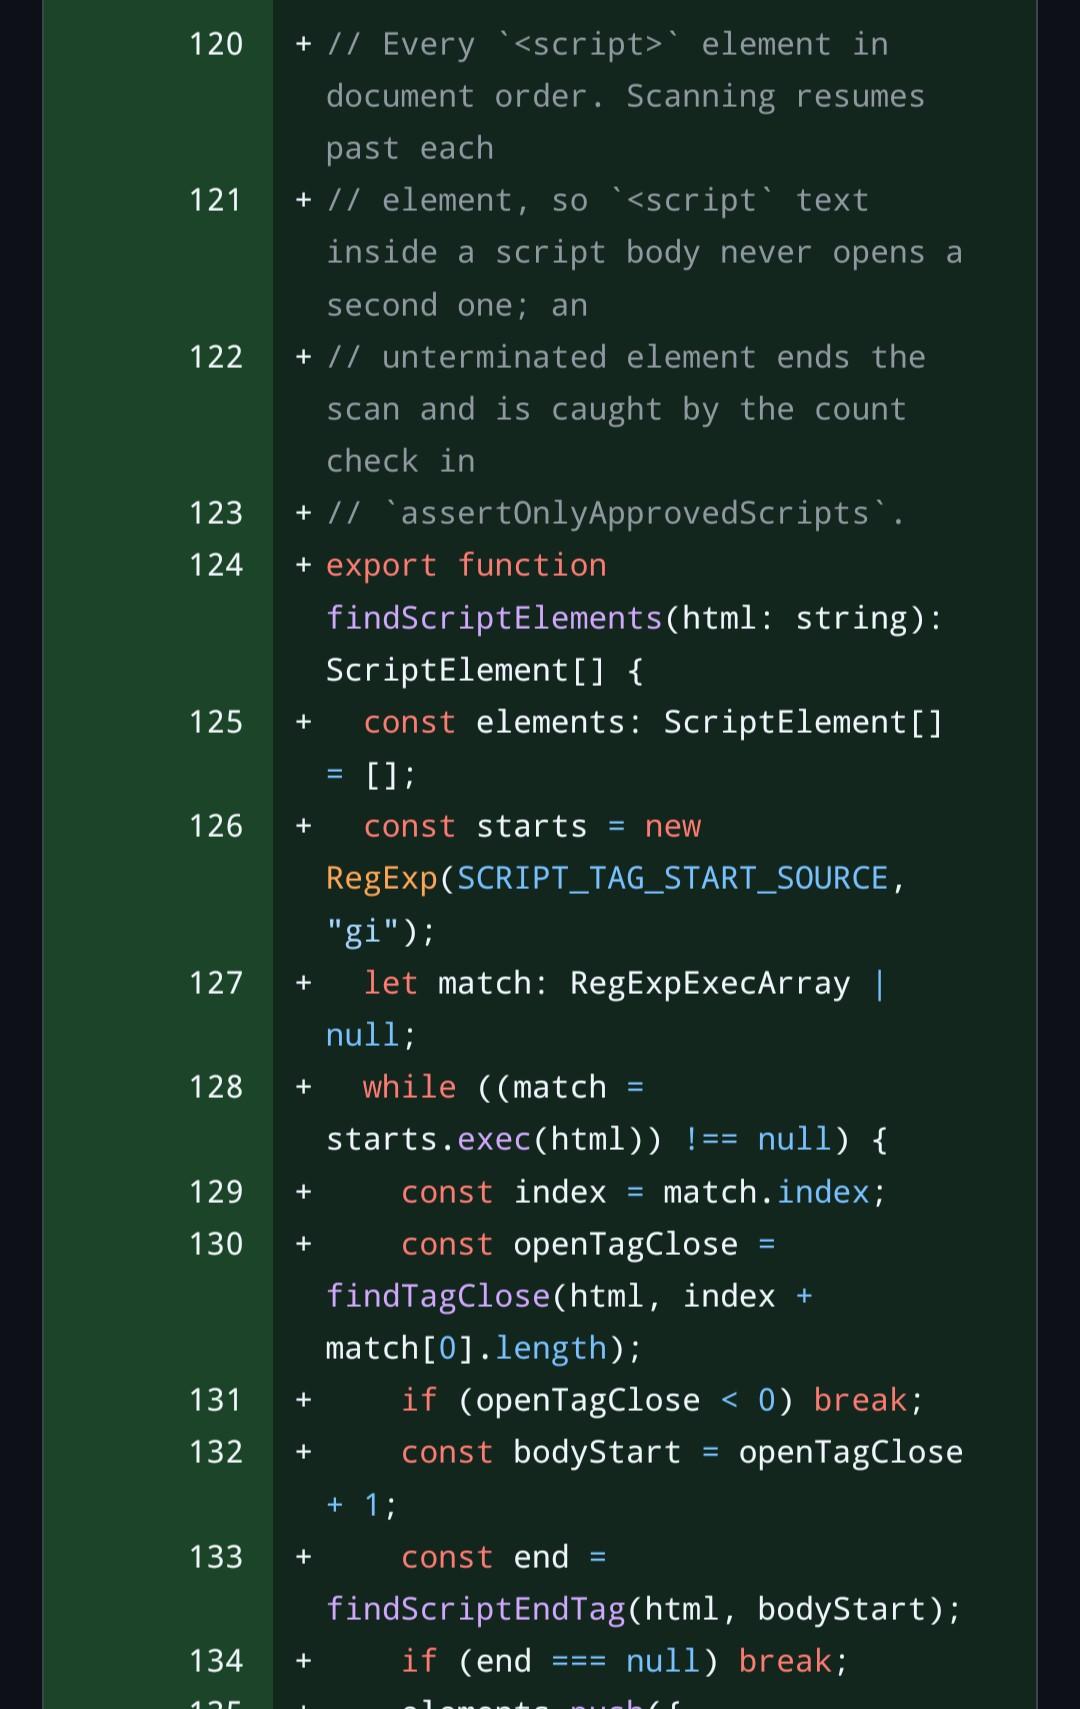
scripttag openings have a corresponding close.So there already IS a proper HTML/js AST parser, which is run, but fuck that too easy. First we call
findScriptElements, which searches for the start of a script start tag with regex, and then uses a handrolled character-level parser to find where it's closed. Amazing! Why? Fuck off that's why! That finds the<script>tag, and then we look for the corresponding</script>tag with a similar but slightly different regex+custom parser combination. Whats that you say? Thats invalid? Not how HTML works? Fuck off! If no end tag is found the start tag is ignored andfindScriptElementsbreaks. So at this point we already know if there are unbalanced script tags, even if we are incorrectly parsing HTML with regex, we just don't use that information.But wait! There so much more! You didn't ask for more? Fuck you! Since the scripts get transformed, and scripts can have strings that look like script tags, we then get a version of the document with all the BODIES of its script tags stripped out. To do that it also uses
findScriptElements, but wait, wasn't that based on regex and would incorrectly match against the very thing we're trying to strip out? Fuck you!What were we doing? Finding unclosed script tags! So we have a list of closed script element locations, a string with all the bodies of its script elements stripped out, so now of course we need a new function
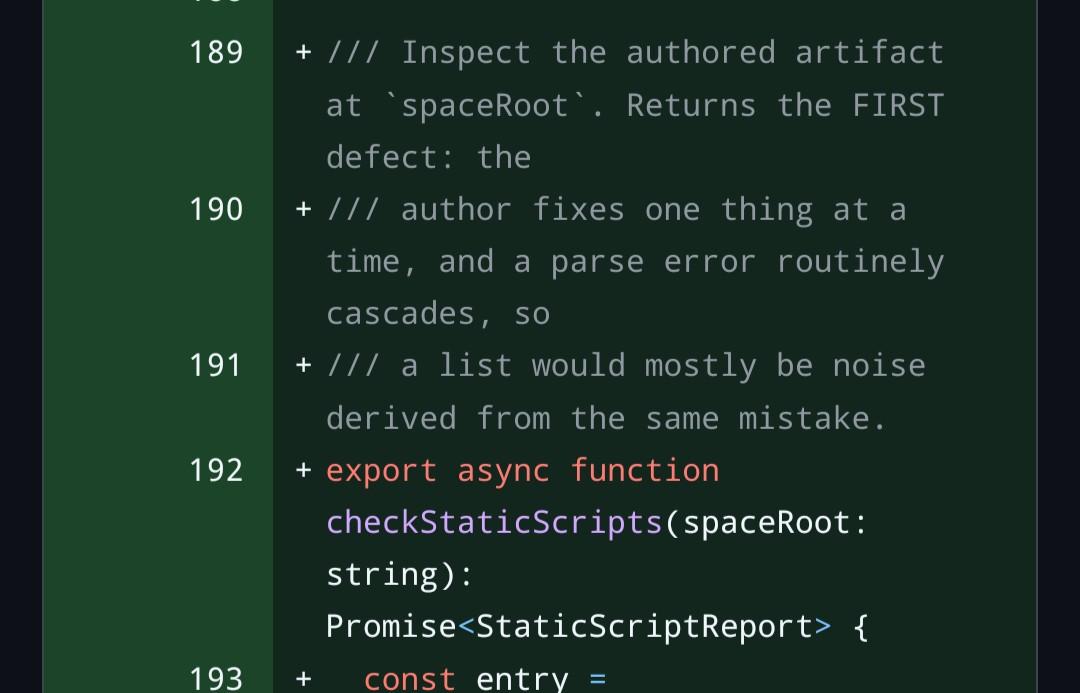
countScriptTagStarts, which is of course just a plain regex search for the opening script tags! With everything we need in hand, which is... Whatever... We then compare if the number of script start tags in the script element stripped html matches the count of the script elements we extracted at the beginning. If that doesn't match we say that... Something... Is wrong!Still not done! Still not released from this torment! You know how validators "scan the whole thing and collect all the errors" and report them, because then you can fix them all at once? Not here! Emit only one error and then bash the LLM at it in a loop! Notice how it says "errors cascade and presenting multiple is just noise" - thats strictly a feature of how shitty their validator is! Usually parse errors are just a different kind of error that shortcircuits further validation that assumes syntactically valid input, so then validation errors don't always propagate! So to compensate for the shitty random walk code churn, we ensure all code that get written in the future has even more preposterously expensive shitty random walk code churn!
Coding!!!! Is !!!! Solved!!!!!!!!!